How an Agency Can Find the Real Questions a Client's Buyers Ask in AI Search
No AI platform exposes buyer prompt logs, but agencies can still build an evidence-backed map of the questions clients' buyers ask in AI search. This guide covers a six-step workflow for discovery, intent scoring, demand validation, coverage checks, and observed AI behavior.
By NarraLoom
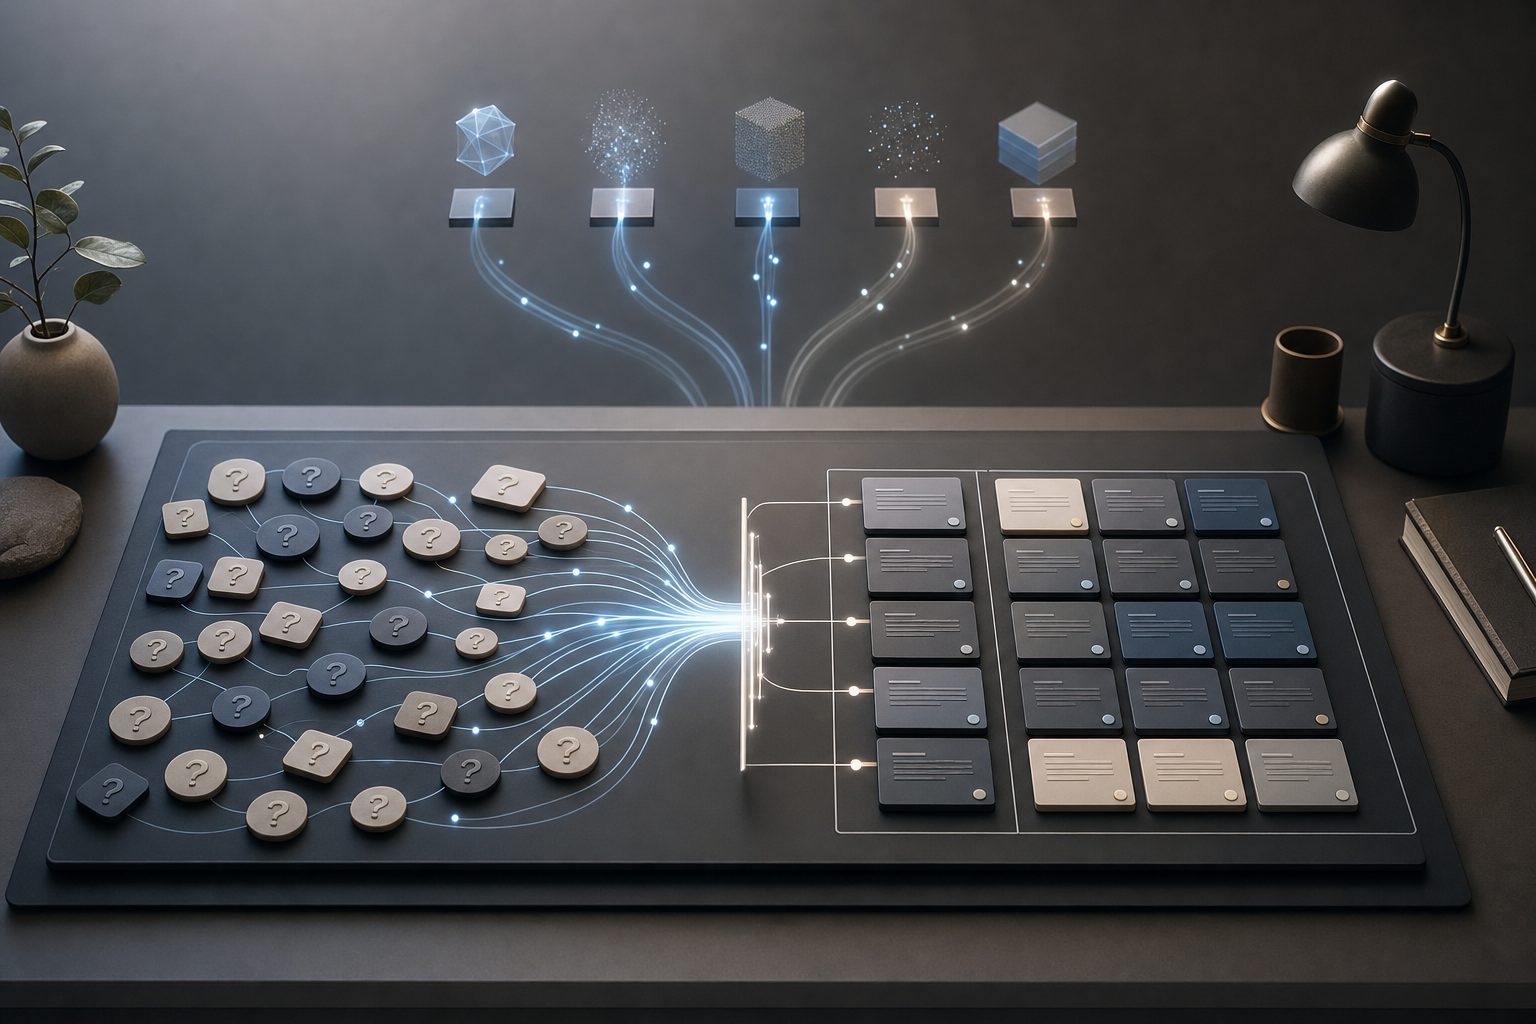
An agency finds the actual questions a client's buyers ask in AI search by combining sources of real buyer language, classifying each question by buyer intent, validating demand with available data, checking what the client's site already answers, and then observing what ChatGPT, Claude, Gemini, and Perplexity actually surface for those questions through repeated testing. No AI platform publishes its prompt logs, so the honest goal is not a literal transcript of buyer prompts. The goal is an evidence-backed map of the buyer-question universe that is strong enough to plan content against and defend in front of a client.
That last part matters more than most guides admit. If you run an agency content or SEO practice, your real problem usually isn't a lack of topic ideas. It's that content planning still starts with brainstorming sessions or generic keyword exports, and when a client asks why a piece was written at all, the answer is a shrug dressed up as a strategy deck. This article walks through a repeatable discovery process you can actually run, how to judge whether a question is commercially relevant, and what has to happen after discovery for the work to turn into results a client can see.
Start With the Honest Limitation
Before any method, set the boundary clearly, because your client will eventually ask about it:
You cannot see the exact prompts an individual buyer types into ChatGPT, Claude, Gemini, or Perplexity. These platforms do not expose query logs the way traditional search tools expose keyword data. Anyone who claims to have direct prompt-level visibility into private AI conversations is overstating what is possible.
What you can build is an evidence-backed approximation of the questions buyers ask, drawn from sources where buyers reveal their language directly, and then verified against what AI engines actually produce when those questions are asked. In practice, this approximation is often more useful than raw keyword volume, because it tells you which questions influence recommendations and which sources AI systems lean on when they answer — a distinction explored further in what AI search engines actually look for.
Framing it this way accomplishes two things: it keeps your claims defensible, and it reshapes the deliverable from a plain keyword list into something closer to a verified picture of buyer demand and the visibility gaps around it — which is a far easier thing to sell as a recurring service.
Buyer-Question Discovery vs. Traditional Keyword Research
Buyer-question discovery is the practice of identifying the full, natural-language questions a client's buyers ask when researching a problem, comparing options, or evaluating a purchase — and determining which of those questions the client currently answers, which competitors occupy, and which represent open visibility gaps.
It differs from keyword research in ways that change how you plan content:
| Traditional keyword research | Buyer-question discovery |
|---|---|
| Short phrases and head terms | Full conversational questions with context (for example, "does this make sense for a ten-person firm?") |
| Ranked by search volume | Ranked by buyer intent, demand signals, and gap evidence |
| Optimized for ranking positions | Optimized for being the answer — in search results and AI responses |
| Ends with a keyword list | Ends with a prioritized, evidence-backed content plan |
| Data source: search tools | Data sources: buyer language, demand data, coverage analysis, and observed AI behavior |
Keyword data still plays a role — as one validation signal, alongside the kind of search demand signals that shape effective content strategies. It just stops being the starting point.
The Discovery Workflow: Six Steps an Agency Can Run
Step 1: Collect real buyer language from primary sources
The most reliable question data does not come from a tool. It comes from places where buyers speak in their own words:
- Sales calls and discovery calls — the questions prospects raise before buying usually echo questions they'd already put to a search bar or an AI assistant.
- Support tickets and chat transcripts — objections, confusions, and questions about how a product fits alongside something else the buyer already uses.
- Client-side sales and account teams — a 30-minute interview with the client's salespeople typically surfaces questions no tool will find.
- Reviews of the client and their competitors — what buyers praise or complain about reveals what they were trying to figure out.
- Communities and forums — industry subreddits, professional groups, and niche forums where buyers ask questions publicly in exactly the phrasing they would use in an AI chat.
- Site search logs and form submissions — first-party evidence of what visitors could not find on their own.
Capture questions verbatim wherever possible. The phrasing itself is the data — a generic query like "best CRM" and a more specific one about which CRM suits a small nonprofit team are fundamentally different questions with different answers, and AI engines treat them differently too. This same collection discipline is what underlies finding the buyer questions a business isn't answering.
Step 2: Expand systematically across the buying journey
Raw collection gives you fragments. To build a complete question universe, expand each core topic across the dimensions buyers actually think in:
- Problem questions — asking why an issue keeps recurring
- Solution questions — asking what fixes it or how to do something specific
- Comparison questions — weighing one option against another given a particular situation
- Fit questions — checking whether something works for a given industry, size, location, or budget
- Cost questions — what something costs and what drives that price
- Risk questions — what can go wrong and how to avoid it
- Process questions — what happens after signing up, buying, or starting
- Recommendation questions — who to use for a given need, nearby or within a niche
Run every core service or product the client offers through this grid. A single service line typically produces dozens of legitimate, distinct buyer questions — which is exactly why a deep audit for one client can reasonably examine hundreds of questions rather than a handful, an approach covered in more depth in turning buyer questions into content AI recommends.
Step 3: Classify each question by buyer intent
Not every real question deserves content. Classify each one:
- Service-intent questions — the asker is evaluating or approaching a purchase decision the client can fulfill. These carry the most commercial weight.
- Problem-aware questions — the asker has the problem the client solves but is not yet evaluating providers. Valuable for earning trust early.
- Adjacent or curiosity questions — related to the topic but disconnected from anything the client sells. Usually deprioritized.
This classification step is what separates a defensible content plan from a big list. It's also the direct answer to the objection every strategist eventually hears — whether these questions are actually worth writing for. A question earns priority when the intent classification, the demand signals, and the gap evidence all point the same direction, not because it sounded good in a brainstorm and not because it chases a snippet, a distinction covered in buyer-question strategy without snippet-chasing.
Step 4: Validate demand with available data
Buyer language tells you the questions are real. Demand validation tells you they are asked at meaningful scale. Use the signals available to you:
- Search volume for the question and its close variants — as an estimate of demand, not a precise count of AI prompts.
- Google Search Console data (with the client's authorized access) — queries the site already appears for, including question-form queries the client never targeted deliberately.
- Frequency across primary sources — a question that shows up in sales calls, support tickets, and community threads independently is validated three ways.
- Geographic normalization — for local or regional clients, demand should be weighed against the actual service area, not national totals.
One caveat worth stating plainly to clients: search volume is a proxy. Conversational AI prompts are typically longer and more specific than typed searches, so a question with modest recorded volume can still be commercially important if the buyer-language evidence supports it. Treat estimated demand and observed behavior as two different kinds of evidence — more on that below.
Step 5: Check what the client already answers — and what AI engines currently surface
Two coverage checks, run with appropriate authorization from the client:
Existing-content coverage analysis. For each priority question, does the client's site answer it clearly, partially, or not at all? "Partially" is the most common and most overlooked state — a page mentions the topic but never actually answers the question a buyer would ask.
Observed AI behavior. Ask the priority questions across ChatGPT, Claude, Gemini, and Perplexity, and record what happens: whether the client is mentioned, which competitors appear, which sources get cited, and how the engines frame the answer. Two disciplines matter here:
- Test repeatedly, not once. AI responses are probabilistic — the same question can produce different answers across sessions and over time. A single response is an anecdote. Repeated observations across engines form a pattern you can present as evidence.
- Verify citations. When an engine cites a source, confirm the source actually exists and says what the answer implies. This keeps your findings defensible when a client's leadership scrutinizes the report.
Where the client is absent and a competitor is consistently surfaced for a service-intent question, you have found a buyer-question gap — the most valuable output of the entire process, because it turns a vague sense that "we should do content" into something concrete: a specific question buyers are asking, a clear picture of who currently owns the answer, and the evidence to back it up. This is the same pattern described in why AI search engines recommend competitors instead of you.
Step 6: Prioritize by evidence, not enthusiasm
The final step compresses everything into a ranked plan. A simple, client-readable prioritization logic:
- Highest priority: service-intent questions with validated demand, no adequate answer on the client's site, and observed competitor presence in AI answers.
- High priority: service-intent questions with validated demand and no adequate answer, where no one clearly owns the answer yet.
- Medium priority: problem-aware questions that feed the service-intent questions above.
- Improve, don't create: questions the client partially answers — often a rewrite outperforms a new page.
- Deprioritize: curiosity questions with weak intent, regardless of volume.
Every item in the plan should trace back to evidence a client can inspect: the question, where it came from, the intent classification, the demand signal, the coverage finding, and the observed AI behavior. That traceability is what makes the plan approvable — and what makes the service renewable.
Estimated Demand vs. Observed AI Behavior
These two evidence types get conflated constantly, and the conflation is where agency credibility quietly erodes. Keep them separate in your reports:
- Estimated demand is modeled data — search volume, question frequency, expansion logic. It tells you how likely a question is to be asked. It is a forecast, and it should be labeled as one.
- Observed AI behavior is snapshot data — what specific engines actually returned for specific questions during specific test runs. It tells you what is happening now, not what will happen permanently. Engines update, answers shift, and today's citation is not tomorrow's guarantee, which is why buyer-question content needs a plan for staying current, not just a launch — a point covered in why buyer-question content decays and what keeps it useful.
When you present findings framed as estimated demand alongside what was repeatedly observed across several engines during a defined audit window, you're making claims you can stand behind. When findings are presented as permanent truth instead, the first time an AI answer changes, the client's trust changes with it.
What Happens After Discovery Is Where Most Agencies Stall
Here's the uncomfortable pattern: most guidance on this topic stops at handing over a list of questions. But a validated question list creates an obligation — someone has to turn those gaps into content, in each client's voice, within each client's compliance boundaries, get it reviewed and approved, publish it through authorized channels, and then measure whether visibility actually moved. Across one client, that is a workload. Across ten clients with different industries, voices, service areas, claim policies, and approval chains, it is an operations problem that brainstorm-driven agencies never face because they never generate this much validated demand in the first place.
This is the layer NarraLoom was built to operate. NarraLoom is a white-label AI Search Visibility operating system and done-for-you fulfillment engine for agencies. The discovery process described above is the front of its operating loop: AI Search Visibility Audits and 300Q deep-dive audits handle real buyer-question discovery, buyer-intent classification, search-demand validation, geographic demand normalization, existing-content coverage analysis, competitor visibility analysis, and repeated observation across ChatGPT, Claude, Gemini, and Perplexity — with citation verification, so the gaps you present to clients are backed by inspectable evidence rather than a single AI response.
Then the loop continues where most tools stop. Verified gaps become evidence-backed topic priorities, which become research-backed, CMS-ready blog articles and platform-native social content — each governed by client-specific voice and brand rules, compliance guardrails, and independent plagiarism and originality checks, then routed through human review and approval before anything publishes through authorized accounts. After publishing, Search Console measurement, indexing tracking, and AI Visibility Progress reporting show what changed, and re-auditing surfaces the next set of gaps. Nothing publishes without configured authorization and required approval, and the QA checks are workflow quality controls, not legal clearance — your judgment and your client's review still matter.
Throughout all of it, the agency keeps the client relationship, pricing, packaging, positioning, and strategy. Everything is delivered under the agency's brand — portal, audits, reports, onboarding, and client experience. NarraLoom runs the infrastructure behind it.
Common Mistakes to Avoid
- Testing an AI engine once and calling it evidence. Single responses are anecdotes. Patterns across repeated tests and multiple engines are evidence.
- Treating volume as the only relevance signal. Long, specific buyer questions often carry low recorded volume and high commercial weight.
- Skipping the coverage check. Recommending new content for a question the client already half-answers wastes budget; a targeted rewrite often does more.
- Presenting AI findings as permanent. Frame everything as observed snapshots from a stated audit window, and build re-auditing into the service.
- Auditing domains without authorization. Coverage and measurement work should always run with appropriate client permission and access.
- Ending the deliverable at the question list. The list is the diagnosis. The recurring value — and the recurring revenue — is in the governed fulfillment and measurement that follow.
FAQ
How are buyer questions discovered?
By combining primary buyer-language sources — sales calls, support tickets, reviews, communities, client sales-team interviews, and first-party site data — with systematic expansion across the buying journey (problem, solution, comparison, fit, cost, risk, process, and recommendation questions). Each candidate question is then classified by intent and validated against available demand data before it enters a content plan.
How do you score commercial intent?
By classifying each question against what the client actually sells. Service-intent questions — where the asker is evaluating or approaching a purchase the client can fulfill — score highest. Problem-aware questions score next, because they feed future purchase decisions. Curiosity questions score lowest regardless of volume. Priority then requires agreement across three signals: intent classification, demand validation, and evidence of a coverage or visibility gap.
Can you see the exact prompts buyers type into ChatGPT or other AI tools?
No. AI platforms do not publish prompt-level logs. What agencies can build is an evidence-backed approximation of the buyer-question universe, verified against what AI engines actually surface when those questions are asked repeatedly across sessions and platforms.
Is buyer-question discovery a one-time audit or an ongoing process?
Ongoing. AI answers shift over time, competitors publish, and clients add services and locations. A one-time audit is a snapshot; re-auditing after content ships shows which gaps closed and which remain, which is what turns the work into a recurring service rather than a one-off report.
How is this different from just asking an AI to generate topic ideas?
AI-generated topic lists are unvalidated guesses — they may or may not reflect real demand, and they carry no evidence of a gap. Buyer-question discovery starts from real buyer language, validates demand, checks existing coverage, and observes actual AI behavior before anything is prioritized. The output is a plan a client can inspect, question, and approve.
Turn Verified Questions Into a Service Your Agency Owns
The agencies winning the AI Search Visibility conversation are not the ones with the biggest topic lists. They are the ones who can walk into a client meeting and say: here are the questions your buyers are actually asking, here is what you already answer, here is what competitors currently occupy in AI answers, and here is the prioritized plan — with the evidence attached. Then they can deliver against that plan, month after month, without their fulfillment operation buckling.
For agencies evaluating AI Search Visibility fulfillment, request the 14-Day Agency Proof. The 14-day evaluation covers your agency and two authorized client or prospect accounts, with six researched blog articles and 24 social adaptations in total. Content is delivered for human review and publication approval in the main NarraLoom portal. No credit card is required; the proof does not include a white-label portal.
Request the 14-Day Agency Proof